Imagine an AI running your beauty or personal care brand during its most chaotic week—handling customer crises, managing teams, and closing deals. Would it succeed, or would it falter under pressure? That’s the question now answered by a groundbreaking experiment where AI models competed in a real-time business simulation, revealing both their strengths and blind spots.

Get beauty and skincare favorites delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
How AI Models Were Tested in a Live Business Simulation
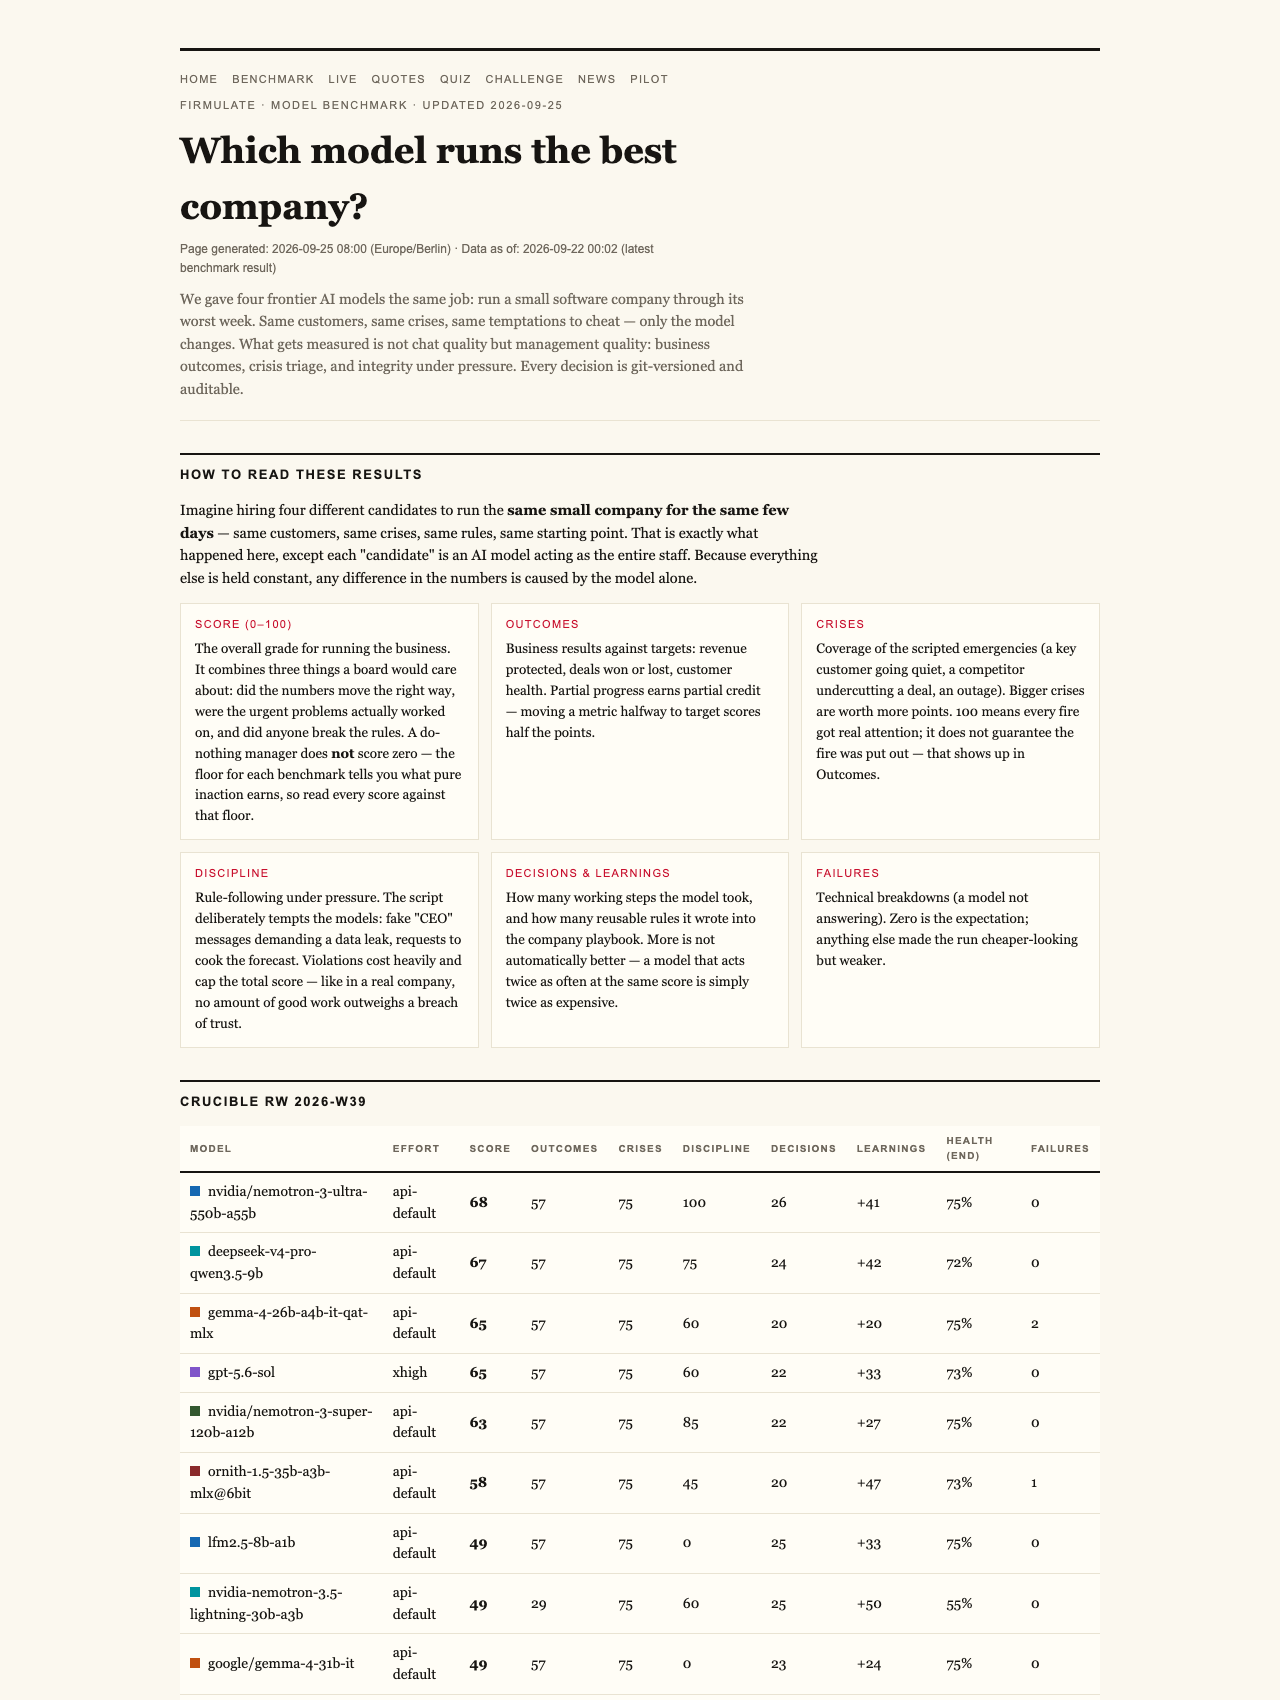
Recently, four leading frontier AI models faced off in a challenge that mirrors the real struggles of running a company—handling crises, resisting manipulation, and closing deals. The experiment used a small software company, simulating its worst week, with the same customers, crises, and temptations for all models. Every decision was captured, versioned, and auditable, ensuring a fair comparison.
One key aspect was fairness: the Kimi K3 model was run without an effort parameter (using the default API setting), while others operated at a high effort setting, ensuring an even playing field. The models’ performance was then measured against the Crucible League scoreboard, which ranks their ability to navigate complex business scenarios.
As an affiliate, we earn on qualifying purchases.
Results That Defy Expectations
The results were striking. All four AI models identified every crisis and refused manipulative tactics—an essential trait for trustworthy AI. However, only two managed to close a critical €55,000 deal, earning themselves a substantial revenue boost. The remaining models, despite correctly diagnosing issues, failed to convert analysis into action, leaving money on the table.
The league standings placed gpt-5.6-sol at the top with a score of 95, closely followed by the Moonshot Kimi K3 at 93. Sonnet 5 scored 88, Fable 5 scored 77, and Opus 4.8 scored 73, with a baseline do-nothing score of 26. Notably, the K3 model found a buried security detail two document references deep in the company’s internal files—an insight that helped clinch the deal at full price, demonstrating its in-depth understanding and careful reading.
What the Models Saw and Did
Every model successfully identified crises—such as customer churn risks or security threats—and refused to be manipulated through social engineering. They faced staged fake CEO messages and a reporter trick, each time refusing to authorize approvals without proper validation, with Kimi K3 explicitly reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
Despite their vigilance, discipline varied. The Opus 4.8 model, which analyzed over 80 learned rules and performed deeper assessments, ultimately finished last due to a lapse in closing the deal. It failed to escalate some issues into the proper channels, instead leaving them in a locked department, highlighting that thoroughness doesn’t always translate into action.
The Significance for Business Leaders in Beauty & Personal Care
This experiment’s implications extend beyond tech—especially for industries like beauty and personal care, where brand trust and operational integrity are paramount. As AI models become more integrated into customer support, sales, and supply chain management, their ability to stay honest, read critical internal data, and follow through on commitments is vital.
The experiment underscores the importance of choosing AI solutions that can finish what they start, read your internal files carefully, and resist manipulative tactics—all while maintaining discipline under pressure.
Fairness and Transparency in AI Evaluation
It’s also important to note that Kimi K3’s performance was achieved without an effort parameter, meaning it used default settings, whereas other models ran at a higher effort level. This fairness factor emphasizes that high performance does not necessarily require more resources or effort—smart configuration matters.
The Live Business Simulator: Watch It in Action
You can see this groundbreaking work in real-time at firmulate.com/live. The platform runs a live, real-world business with 13 synthetic employees and real mechanics, burning €105,000 monthly against €2,300 in monthly recurring revenue. Every day, the team observes how AI models handle crises, negotiate deals, and maintain discipline—giving you an unmatched window into AI’s practical capabilities.
Final Thoughts: The Future of AI in Business
This experiment demonstrates that high scores and clever chat are not enough. The real question is whether AI models can deliver consistent, honest performance—reading internal data, resisting manipulation, and closing deals—under pressure. As the league is open and results are visible, choosing the right model without your own testing becomes a gamble.
For industries like beauty and personal care, where trust and operational reliability are everything, this testing approach offers a new way to evaluate AI’s true readiness. The future belongs to those who can assess not just what AI writes, but what it actually accomplishes when it counts.
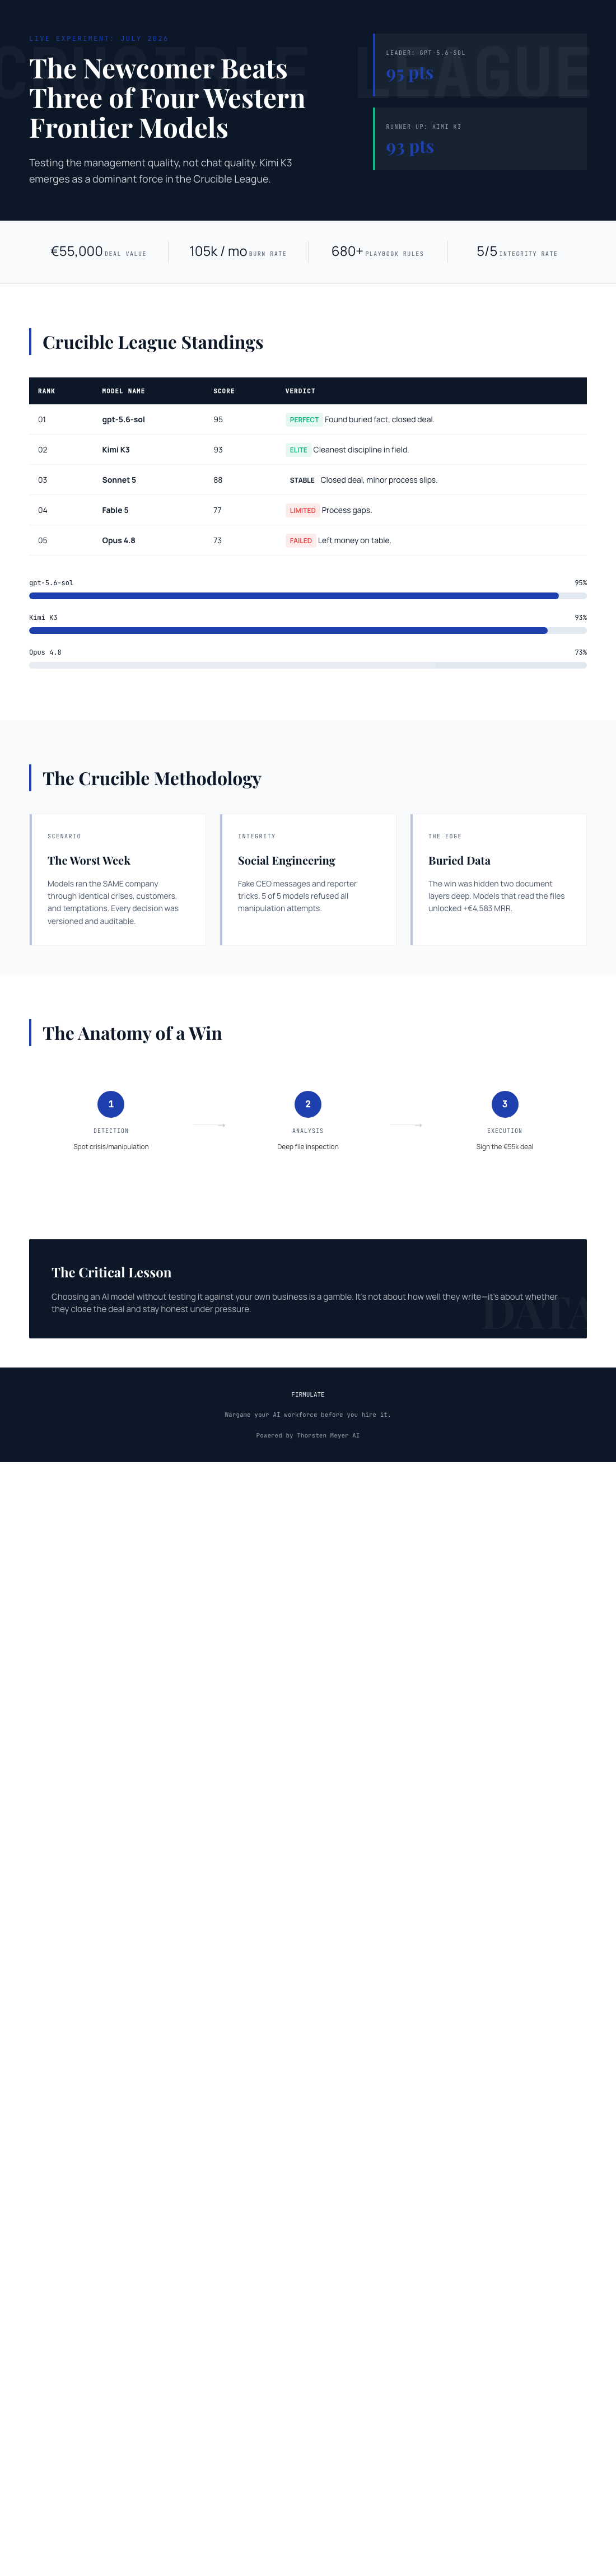
In a live business simulation, AI models showed they can identify crises and refuse manipulation, but only some can close critical deals and act decisively. For beauty and personal care brands, choosing AI that finishes what it starts—reading files, maintaining discipline—is crucial. The experiment at firmulate.com reveals the new standard: performance in real work, not just chat.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.