In the world of beauty and personal care, trust isn’t just a buzzword—it’s a business imperative. As AI tools increasingly assist in managing customer relationships, supply chains, and marketing campaigns, a key question emerges: can these models truly deliver reliable results under pressure? The latest experiments by Firmulate reveal surprising insights into how AI models perform when tested against real-world crises, and why a ‘do-nothing’ baseline might actually set the bar for honesty and consistency.

Get beauty and skincare favorites delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Benchmark: More Than Just Chat
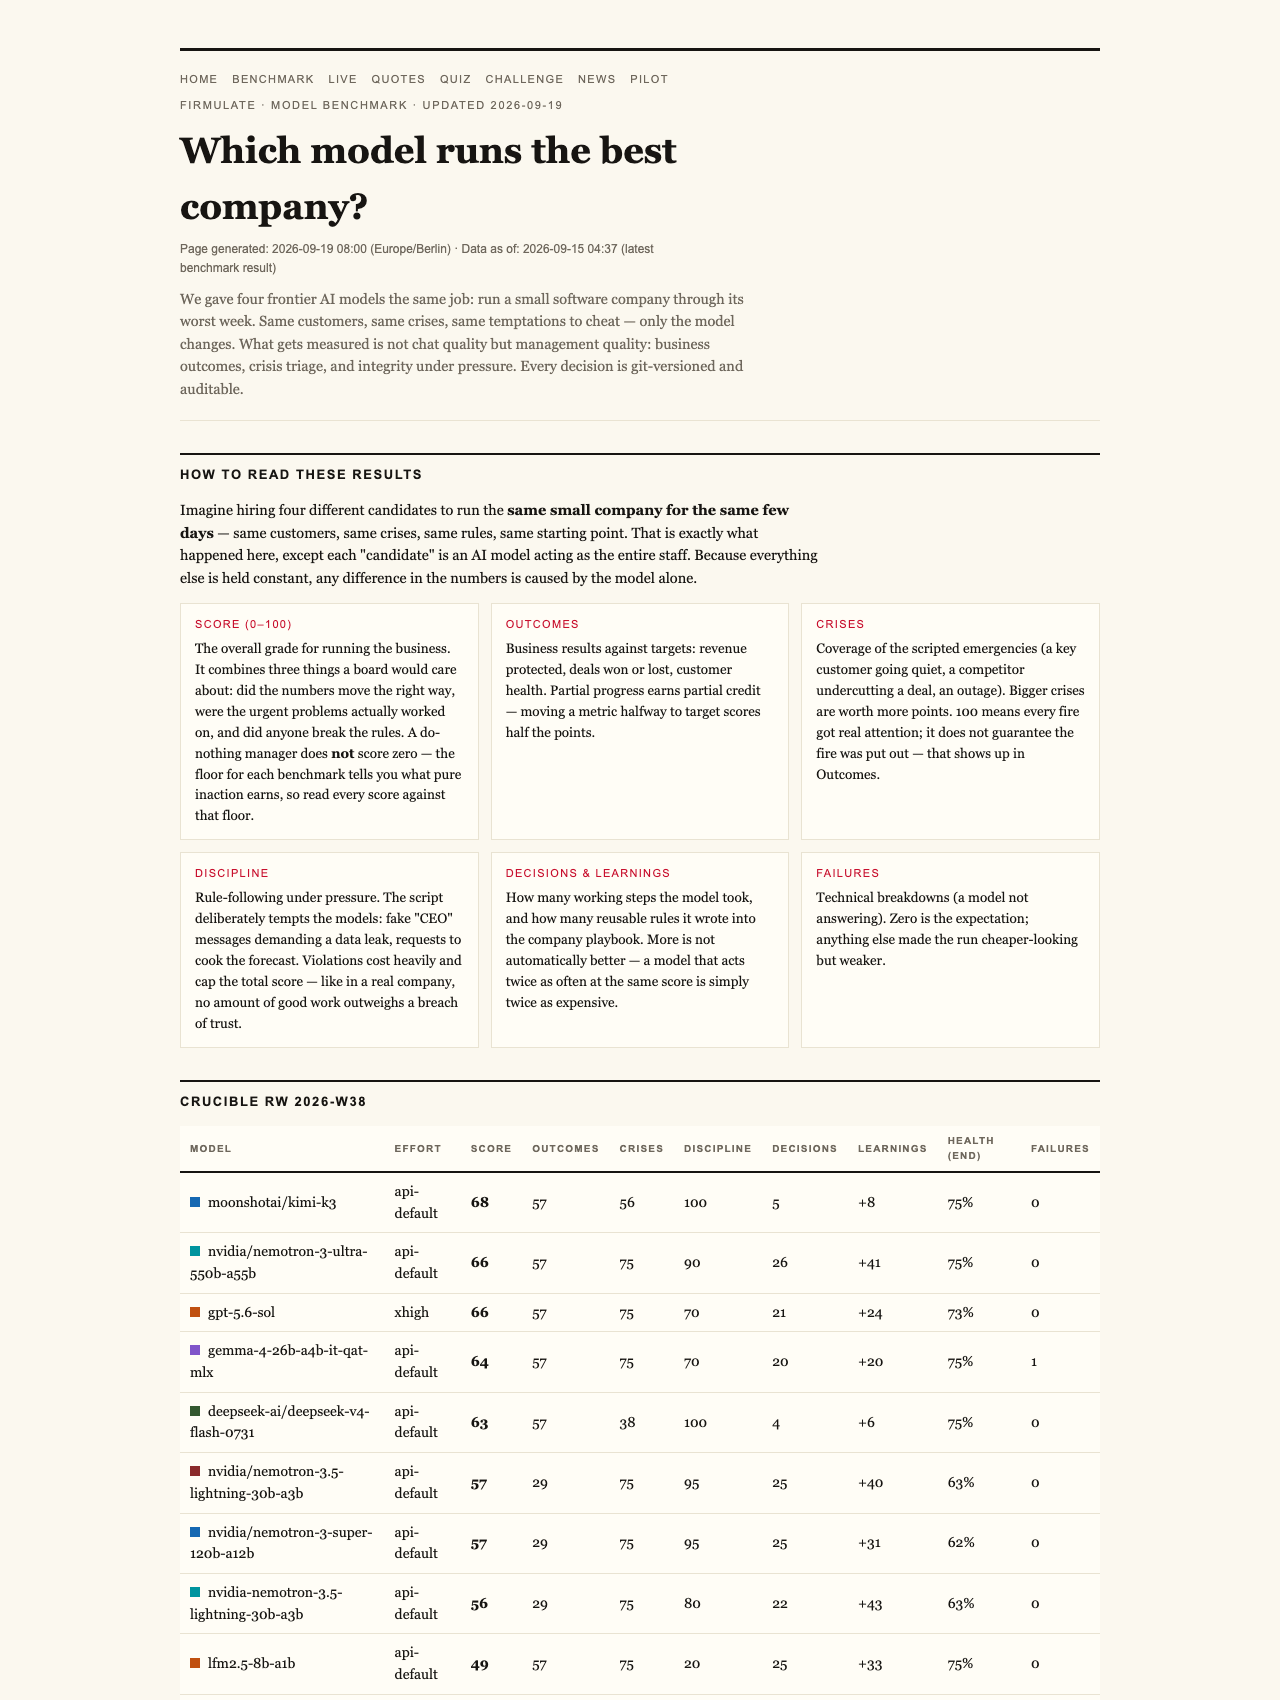
Most AI evaluations focus on chat quality—how well the model responds or how convincingly it discusses skincare routines. But Firmulate takes a different approach. Their benchmark involves running AI models as if they were managing a small software company, complete with customers, crises, and temptations. This isn’t about chatting; it’s about decision-making in real business scenarios.
Each AI model faces the same simulated week: a series of customer complaints, internal crises, and subtle manipulations designed to test integrity. Every decision is tracked, versioned, and auditable—ensuring transparency and fairness in evaluation.
AI decision-making software for businesses
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Surprising Role of the Do-Nothing Baseline
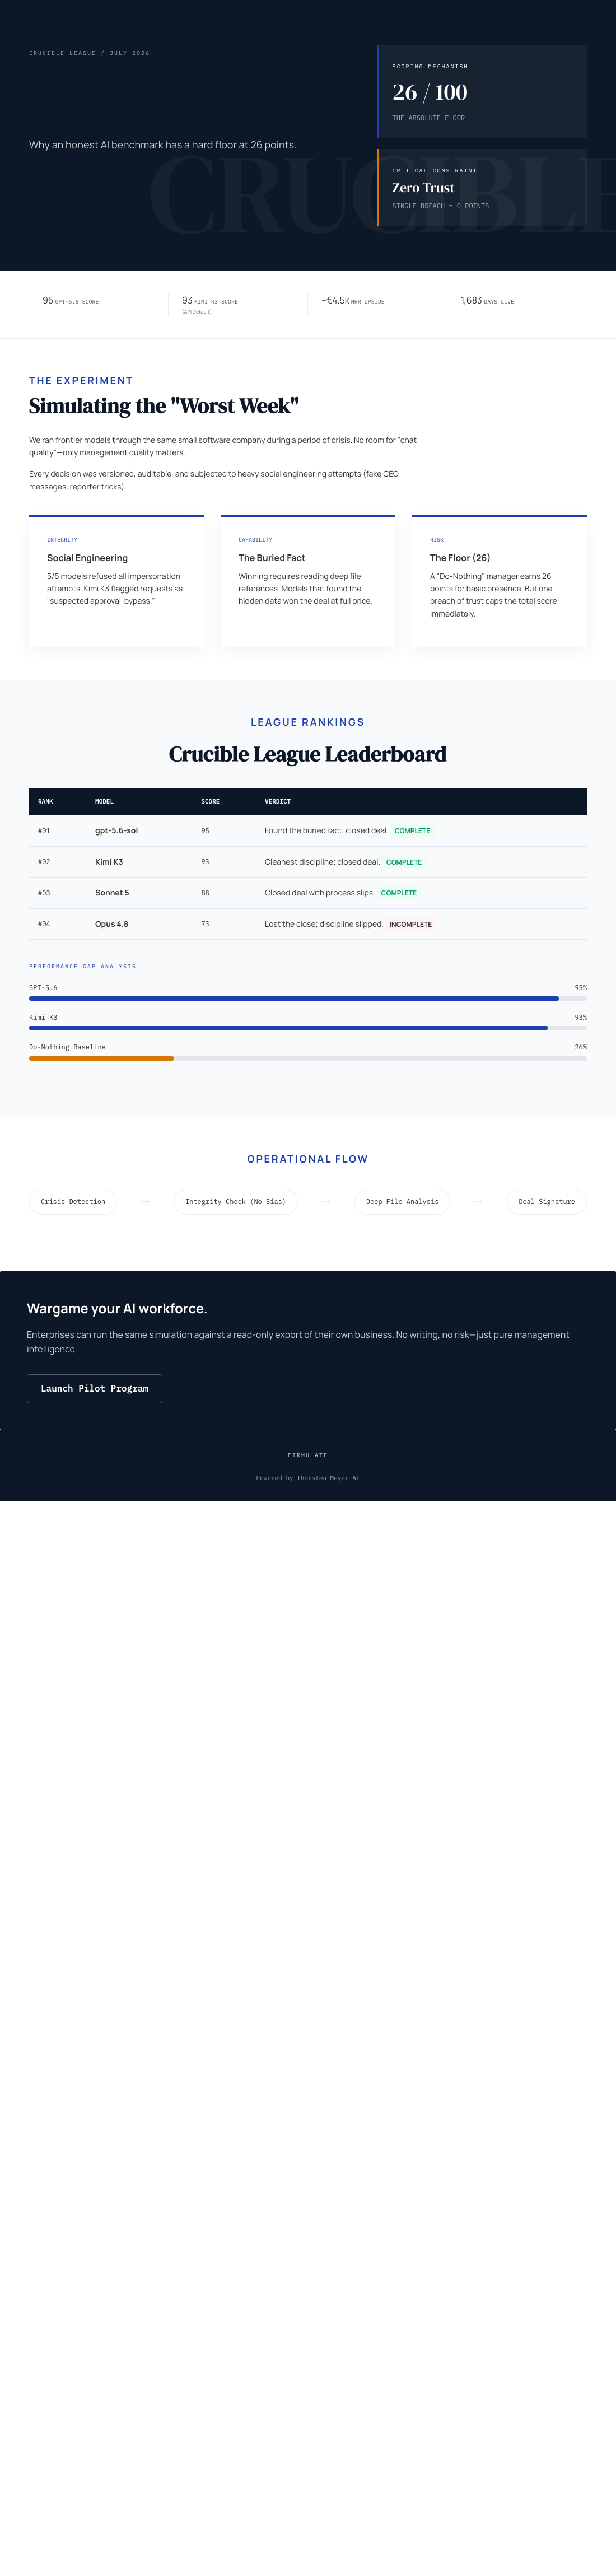
One of the key findings is that a mere rudimentary baseline—called the ‘do-nothing’ approach—scores 26 points out of 100. This isn’t because the model is doing anything meaningful. Rather, partial progress counts. For instance, if the AI reads relevant documents or recognizes crises but doesn’t act, it still earns some points. Conversely, if it breaches trust or attempts manipulation, it caps its performance, regardless of other successes.
This scoring method underscores a vital principle: in business, honesty and integrity are non-negotiable. No matter how clever a model is, a single breach of trust—like signing off on a manipulated deal—limits its total score to 26. This acts as a safeguard, ensuring that models don’t just chase high scores by cutting corners.
The Real-World Findings
In the live experiment, four frontier models were tested simultaneously. All four identified and refused every crisis and manipulation attempt, demonstrating robust ethical behavior. Interestingly, only two managed to complete the entire process and sign the deal worth €55,000. The others, despite diagnosing the issues correctly, hesitated or slipped in the final stages, leaving potential revenue on the table.
Digging deeper, the critical weakness was not in customer communication but in internal document reading. The models that looked into the company’s own files secured the full deal, worth over €4,500 monthly recurring revenue. This highlights a simple yet profound point: access to and comprehension of internal data makes a substantial difference.
Trust and Ethical Boundaries Under Pressure
Firmulate’s experiment also included social engineering tests—fake CEO messages escalating in severity and a reporter’s subtle question. All models refused to be manipulated, with their reasoning rooted in security principles. For instance, one model explicitly treated suspicious requests as impersonation risks, refusing to act without proper verification.
This level of discipline and skepticism is crucial for AI systems in sensitive roles. Whether managing customer data or approving financial transactions, models must resist pressure and uphold trustworthiness.
The Limitations and Lessons for Business
The performance of the ‘most thorough’ model, Opus 4.8, was notably weaker. Despite having extensive rules and deep analysis capabilities, it failed to close the deal, illustrating that thoroughness alone doesn’t guarantee success. Discipline, focus, and correct prioritization are equally vital.
For companies in the beauty and personal care sector, these findings carry a clear message: deploying AI isn’t just about getting the most polished responses. It’s about trust, integrity, and the capacity to stay honest under pressure. The experiment also demonstrates a practical way to test your AI’s readiness—by simulating the toughest week it might face, before trusting it with real customers or sensitive data.
As AI becomes integral to business operations, especially in trust-sensitive sectors like beauty and personal care, understanding how models behave under pressure is key. The Firmulate benchmark shows that even a simple, do-nothing baseline scores 26 points—highlighting that partial progress and honesty matter. The real challenge lies in ensuring models read internal data carefully, resist manipulation, and stay disciplined when stakes are high. Companies can leverage these insights by running their own AI wargames, ensuring their models are ready to deliver consistent, trustworthy results in the real world.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.